Ready-to-deliver AI training datasets
175 AI training datasets across audio, images, video, text and question banks. Every dataset comes with samples, is quoted per order and is delivered offline.
175 datasets
U.S. Patent PDF Document Dataset
Collected from U.S. patent grant documents, this dataset includes the original PDF files, preserving the documents’ exact appearance without any secondary processing. It can be…
Contact for price
U.S. Patent Assignment Records Dataset
Collected from U.S. patent assignment data, this dataset includes records related to assignments—such as registration details, assigning parties, receiving parties, and associated…
Contact for price
U.S. Patent Maintenance Fee Incident Dataset
Collected from U.S. patent maintenance fee data, this dataset includes records of maintenance‑fee‑related events along with code descriptions, preserving the original record…
Contact for price
European Patent Structured Information Dataset
Collected from European patent data, this dataset includes parsed, structured information (such as bibliographic records, classifications, citations, and applicant details)…
Contact for price
European Patent Full-Text Dataset
Collected from European patent literature, this dataset includes full-text XML records, preserving the original document structure and content without any secondary processing. It…
Contact for price
United States Patent Gazette Information Dataset
Collected from U.S. patent gazette data, this dataset includes XML records related to the gazettes, preserving the original record structure and field values without any secondary…
Contact for price
Full-text dataset of U.S. patent grants
Collected from U.S. patent grant documents, this dataset includes full-text XML records and technical descriptions, preserving the original document structure and content without…
Contact for price
Full-Text Dataset of U.S. Patent Applications
Collected from U.S. patent application publication documents, this dataset includes the full-text XML of the published applications along with accompanying image files, preserving…
Contact for price
U.S. Text Trademark Dataset
Structured records extracted from U.S. trademark data, containing information on trademark applications and registrations, preserving the original fields and field values without…
Contact for price
Chinese Textual Trademark Dataset
Structured records extracted from Chinese trademark data, containing information on trademark applications and registrations, including fields such as registration/application…
Contact for price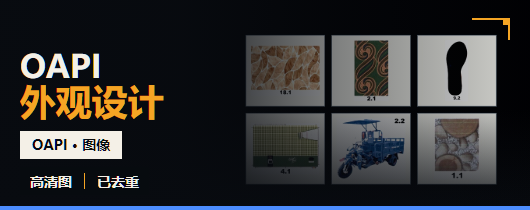
Design Drawings Dataset for the African Region (OAPI)
Design data collected from the African region (OAPI), including design drawing files, with the original images and file codes preserved and no secondary processing applied…
Contact for price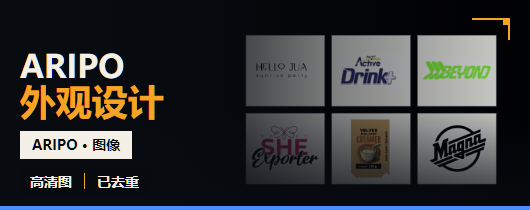
Design Drawings Dataset for the African Region (ARIPO)
Design data collected from the African region (ARIPO), including design drawing files, with the original images and file codes preserved and no secondary processing applied…
Contact for price
Argentine Pattern Dataset
Pattern data files collected from Argentina, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Algerian Pattern Dataset
Pattern data files collected from Algeria, containing pattern‑type images. The original images and file metadata are preserved, with no secondary processing applied. Applications…
Contact for price
Azerbaijan Pattern Dataset
Pattern data files collected from Azerbaijan, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied…
Contact for price
Vietnamese Industrial Design Drawing Dataset
Design data collected from Vietnam, including design drawing files, with the original images and file codes preserved and no secondary processing applied. Applications include…
Contact for price
Vietnamese Pattern Dataset
Pattern data files collected from Vietnam, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Spanish Pattern Dataset
Pattern data files collected from Spain, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Portuguese Pattern Dataset
Pattern data files collected from Portugal, containing pattern‑type images, with the original images and file encodings preserved and no secondary processing applied. Applications…
Contact for price
Finnish Pattern Dataset
Pattern data files collected from Finland, containing pattern‑related images, with the original images and file metadata preserved and no secondary processing applied…
Contact for price
U.S. Graphic Trademark Dataset
Trademark data collected from the United States, including trademark image files, with the original images and file codes preserved and no secondary processing applied…
Contact for price
Romanian Pattern Dataset
Pattern data files collected from Romania, containing pattern‑type images. The original images and file encodings are preserved, with no secondary processing applied. Applications…
Contact for price
Irish Pattern Dataset
Pattern data files collected from Ireland, containing pattern‑related images, with the original images and file encodings preserved and no secondary processing applied…
Contact for price
Georgian Pattern Dataset
Pattern data files collected from Georgia, containing pattern‑type images. The original images and file encodings are preserved, with no secondary processing applied. Applications…
Contact for price
Cambodian Pattern Dataset
Pattern data files collected from Cambodia, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Slovakia Pattern Dataset
Pattern data files collected from Slovakia, containing pattern‑type images, with the original images and file encodings preserved and no secondary processing applied. Applications…
Contact for price
Czech Pattern Dataset
Pattern data files collected from the Czech Republic, containing pattern‑type images, with the original images and file encodings preserved and no secondary processing applied…
Contact for price
Italian Pattern Dataset
Pattern data files collected from Italy, containing pattern‑related images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Greek Pattern Dataset
Pattern data files collected from Greece, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Brazilian Industrial Design Image Dataset
Design data collected from Brazil, including design drawing files, with the original images and file codes preserved and no secondary processing applied. Applications include…
Contact for price
Austrian Pattern Dataset
Pattern data files collected from Austria, containing pattern‑type images, with the original images and file encodings preserved and no secondary processing applied. Applications…
Contact for price
Indian Industrial Design Image Dataset
Design data collected from India, including design drawing files, with the original images and file codes preserved and no secondary processing applied. Applications include…
Contact for price
Indian Trademark Gazette Design Data Set
Trademark data collected from India, including trademark image files, with the original images and file codes preserved and no secondary processing applied. Applications include…
Contact for price
South African Industrial Design Drawing Dataset
Design data collected from South Africa, including design drawing files, with the original images and file codes preserved and no secondary processing applied. Applications…
Contact for price
North Macedonia Pattern Dataset
Pattern data files collected from North Macedonia, containing pattern‑type images, with the original images and file encodings preserved and no secondary processing applied…
Contact for price
Croatian Pattern Dataset
Pattern data files collected from Croatia, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Ukrainian Pattern Dataset
Pattern data files collected from Ukraine, containing pattern‑type images, with the original images and file metadata preserved and no secondary processing applied. Applications…
Contact for price
Danish Pattern Dataset
Pattern data files collected from Denmark, containing pattern‑type images. The original images and file encodings are preserved, with no secondary processing applied. Applications…
Contact for price
Hong Kong, China Pattern Dataset
Pattern data files collected from Hong Kong, China, containing pattern‑type images. The original images and file encodings are preserved, with no secondary processing applied…
Contact for price
Chinese Graphic Trademark Dataset
Graphic trademark image files collected from Chinese trademark data, containing graphical representations of trademarks in the application and registration stages. The original…
Contact for price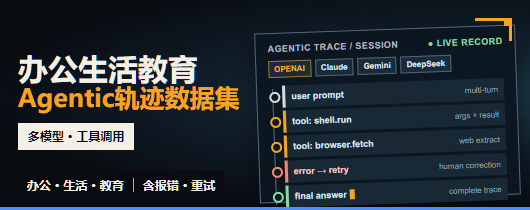
Office Life Education Agentic Trajectory Dataset
It collects real‑world agent interaction data from online sources, with each record fully capturing the agent’s workflow: system prompts, multi‑turn dialogues, tool definitions…
Contact for price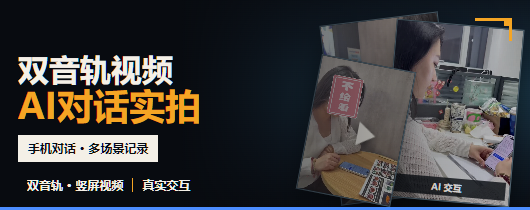
Dual-track AI dialogue real-world video dataset
This dataset comprises vertical‑format, dual‑audio‑track videos of real users interacting with AI on their smartphones, covering everyday and work scenarios such as restaurant…
Contact for price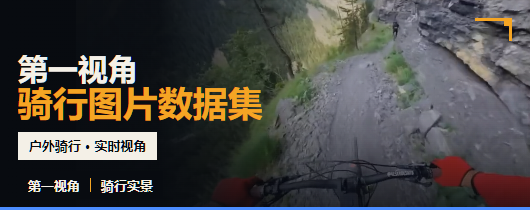
First-person cycling image dataset
This dataset contains first-person outdoor cycling images, featuring elements such as bicycle handlebars, mountain canyons, rock faces, and natural landscapes. It can be used for…
Contact for price
Multinational Film and Television Video Metadata Dataset
This dataset includes video files of movies and TV series from over 30 countries and regions, including the U.S., U.K., Japan, South Korea, and more. It covers basic metadata…
Size: 6,151 items
Contact for price
Pet Vocalization Emotion Annotation Dataset
This dataset contains audio recordings of cat and dog vocalizations, along with corresponding emotion and behavioral state labels. It is suitable for research and development in…
Size: 50,000+
$0.88per piece
Mandarin Chinese Spoken Audio Database
The Mandarin Chinese spoken language corpus comprises 566 hours of audio, with 188.7 hours recorded in a single channel. The recordings are in Chinese and were made by 219…
Size: 566 hours
Contact for price
Live-streamed dialect speech database
A dialect speech database totaling 157,614 hours. The data is primarily sourced from video platforms such as Douyin, Kuaishou, Haokan, Xigua Video, Bilibili, and iQIYI, and…
Size: 166114 hours
Contact for price
Smart Home Voice Data – Chinese
The smart home voice database comprises a total of 1,852 hours of recordings. The spoken language is Chinese, and the recordings were made in China. The transcribed text covers 11…
Size: 1852 hours
Contact for price
Intelligent Cockpit Human–Machine Interaction Speech Dataset – Internal Combustion Engine Vehicles
The intelligent cockpit human–machine interaction speech dataset comprises a total of 613 hours. The recording language is Chinese, and the recordings were made in China. The…
Size: 613 hours
Contact for price
Chinese–English Wake Word Speech Database
The database contains 1,561.12 hours of speech data, including 3,936,003 wake-up-word speech files. Database languages: Chinese and English ◎ Recording area: China ◎ Wake-up words…
Size: 1561.12 hours
Contact for price
Mandarin Chinese speech data
The Mandarin Chinese speech database contains a total of 3,002 hours of recordings. The transcribed texts cover 15 domains, including smart home, autonomous driving, and…
Size: 3,002 hours
Contact for price
Mandarin Chinese speech synthesis data
The Mandarin Chinese speech synthesis database contains a total of 654 hours and 657,000 entries. The recorded texts cover 15 domains, including smart home, autonomous driving…
Size: 654 hours
Contact for price
Smart Home Voice Data - English
The smart home voice database comprises a total of 315 hours of recordings. The recording language is English, and the recordings were made in the United States. The transcribed…
Size: 315 hours
Contact for price
Smart Cockpit Voice Interaction Dataset
The intelligent cockpit voice interaction dataset comprises a total of 3,164 hours. The recordings are in Chinese and were collected in China, involving 260 speakers aged between…
Size: 3,164 hours
Contact for price
Far-field voiceprint speech data
The voice database comprises a total of 20,253 hours of recordings. The recording language is Chinese, and the recordings were collected in China. A total of 511 speakers were…
Size: 20,253 hours
Contact for price
Arabic Speech Database
The Arabic speech database comprises 899 hours of audio, containing 448,611 sentences. It has a sampling rate of 16,000 Hz and a bit depth of 16 bits. A total of 1,348 speakers…
Size: 899 hours
Contact for price
Russian speech database
A Russian speech database, totaling 1,279 hours and 517,548 sentences. The sampling rate is 16,000 Hz, with a bit depth of 16 bits. A total of 939 speakers were invited to record…
Size: 1,279 hours
Contact for price
Kazakh phonetic database
The Kazakh speech database comprises 1,275 hours of audio and 446,250 sentences. It has a sampling rate of 16,000 Hz and a bit depth of 16 bits. A total of 736 speakers were…
Size: 1,275 hours
Contact for price
Older adult Mandarin Chinese data
The Chinese speech database for elderly speakers comprises a total of 793 hours of recordings. The recorded language is Chinese, and the recordings were made in China. The…
Size: 793 hours
Contact for price
Model-generated Chinese emotional synthetic speech database
The model-generated Chinese emotional synthetic speech database contains a total of 462,000 entries, collected from 92 speakers. The synthesis engines used include iFLYTEK…
Size: 462,000 items
Contact for price
Intelligent Cockpit Human-Machine Interaction Speech Dataset – New Energy Vehicles
The intelligent cockpit human–machine interaction speech dataset comprises a total of 10,854 hours. The recording language is Chinese, and the recordings were made in China. The…
Size: 10,854 hours
Contact for price
Ambient noise
The noise scene database contains a total of 37.4 hours of audio. It was collected in real-world settings and includes 17 distinct scene categories. Recordings were made using…
Size: 37.4 hours
Contact for price
Thai speech dataset
A Thai speech database totaling 100 hours, with a sampling rate of 16,000 Hz and a bit depth of 16 bits. The speakers are native Thai speakers aged between 7 and 70 years old…
Size: 100 hours
Contact for price
A database of dialect-synthesized speech generated by a model.
The model-generated dialect speech synthesis database contains a total of 9.1 million entries, collected from 36 speakers. The synthesis engines used are iFLYTEK, Volcano, and…
Size: 9.1 million entries
Contact for price
Indonesian speech dataset
An Indonesian speech database totaling 100 hours. Sampling rate: 16,000 Hz; bit depth: 16 bits. The speakers are native Indonesian speakers aged between 7 and 70 years old…
Size: 100 hours
Contact for price
Cantonese Dialect Speech Database
The Cantonese dialect speech database contains a total of 768 hours of audio. The data types include read speech and conversational speech, with 618.8 hours of read speech and 149…
Size: 768 hours
Contact for price
Sichuan Dialect Speech Database
The Sichuan Dialect Speech Database contains a total of 688 hours of audio. The data types include read speech and conversational speech, with 341 hours of read speech and 347…
Size: 1,285 hours
Contact for price
Shanghai Dialect Speech Database
The Shanghai Dialect Speech Database comprises a total of 340 hours of audio. The data includes both read speech and conversational speech, with 174 hours of read speech and 166…
Size: 340 hours
Contact for price
Vietnamese speech dataset
A Vietnamese speech database totaling 100 hours, with a sampling rate of 16,000 Hz and a bit depth of 16 bits. The speakers are native Vietnamese speakers from Hanoi and Ho Chi…
Size: 100 hours
Contact for price
Meeting data
The conference speech audio database contains 639 meetings, totaling 381 effective hours. The recording language is Chinese, and the recordings were made in China. The content…
Size: 666 hours
Contact for price
Tibetan Speech Database
The Tibetan speech database comprises a total of 1,204.8 hours of audio. It features a sampling rate of 16,000 Hz and a bit depth of 16 bits. The data has been transcribed and…
Size: 1204.8 hours
Contact for price
Synthetic Speech Database
A synthetic speech database totaling 300,000 hours. The data is primarily sourced from audio platforms such as Himalaya, Yunting, Lizhi FM, audiobooks, and Tencent Music. It…
Size: 300,000 hours
Contact for price
Voiceprint speech data
The speech database comprises a total of 671 hours of recordings. The spoken language is Chinese, and the recordings were collected across China. A total of 7,986 speakers from…
Size: 671 hours
Contact for price
1,300-person voiceprint speech dataset
The voice database comprises a total of 602 hours of recordings. The recording language is Chinese, and the recordings were made in China. A total of 1,300 speakers from various…
Size: 602 hours
Contact for price
Model-generated English synthetic speech database
The model-generated English synthetic speech database comprises a total of 1.51 million entries, collected from 61 speakers. The synthesis engines used are from Volcano, Microsoft…
Size: 1.51 million items
Contact for price
Chinese Multi-Person Synthesis Database
The Chinese multi-person speech synthesis database contains a total of 12.76 hours of audio, comprising 12,519 utterances. The recording language is Chinese, and the recordings…
Size: 12.76 hours
Contact for price
Emotional Speech Synthesis Database
The Chinese emotional speech synthesis database comprises a total of 40 hours of recordings. The recording language is Chinese, and the recordings were made in China. Primarily…
Size: 40 hours
Contact for price
Code dataset
The code dataset includes six programming languages, totaling 9,680,258 coding problems. The supported languages are C, C++, Java, JavaScript, Python, and SQL. The programming…
Size: Question 9680258
Contact for price
News Text Dataset
A news text dataset comprising six websites, with a total of 3,674,341,167 text entries. The websites include Sina, The Paper, People’s Daily Online, Sohu, NetEase, and Xinhua Net…
Size: 3,674,341,167 items
Contact for price
Multilingual Text Dataset
A multilingual text dataset containing texts from 34 countries, totaling 4,726,596 entries. The text content covers everyday life domains such as finance, sports, entertainment…
Size: 4,574,293 items
Contact for price
Thai–English Parallel Corpus
The Thai–English parallel corpus comprises a total of 1,954,681 entries, covering texts such as news articles, everyday expressions, and addresses.
Size: 1,954,681 items
Contact for price
English Speech Summarization Dataset
The audio summary dataset comprises a total of 466 hours, sourced from publicly available online films and TV series, encompassing 15 episodes in total. The data includes episode…
Size: 466 hours
Contact for price
Hakka Dialect Database
The Hakka dialect speech database contains a total of 513 hours of recordings. The recorded language is the Hakka dialect, and the recordings were made in Meizhou, China. A total…
Size: 513 hours
Contact for price
Hearing-Impaired Speech Database
The hearing-impaired speech database comprises 315 speakers and spans 341 hours of audio. It was recorded with native Chinese-speaking participants, at a sampling rate of 16,000…
Size: 341 hours
Contact for price
Qingdao Dialect Speech Database
The Qingdao Dialect Speech Database contains a total of 309 hours of recordings. The recorded language is the Henan dialect, and the recordings were made in Henan Province, China…
Size: 309 hours
Contact for price
Jinan Dialect Speech Database
The Jinan Dialect Speech Database contains a total of 208 hours of recordings. The recorded language is the Jinan dialect, and the recording location is Jinan, China. A total of…
Size: 208 hours
Contact for price
Henan Dialect Speech Database
The Henan Dialect Speech Database contains a total of 450 hours of recordings. The recorded language is the Henan dialect, and the recordings were made in Henan Province, China. A…
Size: 737 hours
Contact for price
Indonesian speech database
An Indonesian speech database totaling 205 hours. The sampling rate is 16,000 Hz, with a bit depth of 16 bits. The database has been transcribed and annotated by professional…
Size: 205 hours
Contact for price
Mandarin Pronunciation Database of Taiwan
The Mandarin Chinese speech database from Taiwan comprises a total of 720.8 hours of audio. It features a sampling rate of 16,000 Hz and a bit depth of 16 bits. The data is…
Size: 720.8 hours
Contact for price
Uyghur Speech Database
The Uyghur speech database contains a total of 2,026 hours of audio. It has a sampling rate of 16,000 Hz and a bit depth of 16 bits. The data has been transcribed and annotated by…
Size: 2026 hours
Contact for price
Cantonese Speech Database
The Cantonese speech database comprises a total of 965 hours. It features a sampling rate of 16,000 Hz and a bit depth of 16 bits. The data has been transcribed and annotated by…
Size: 965 hours
Contact for price
Thai speech database
A Thai speech database totaling 530 hours, with a sampling rate of 16,000 Hz and a bit depth of 16 bits. The speakers are native Thai speakers who recorded in quiet environments…
Size: 530 hours
Contact for price
Vietnamese speech database
A Vietnamese speech database totaling 521 hours. Sampling rate: 16,000 Hz; bit depth: 16 bits. The speakers are native Vietnamese speakers aged between 14 and 51. Transcriptions…
Size: 521 hours
Contact for price
Far-field voice assistant speech database
The far-field voice assistant speech database comprises 6,200 hours of audio, recorded with the participation of 450 speakers from both northern and southern China, predominantly…
Size: 6,200 hours
Contact for price
Japanese speech database
The Japanese speech database contains a total of 295,083 entries, spanning 245 hours. Recordings were made in Japan, with speakers including both adults and children. The corpus…
Size: 245 hours
Contact for price
Shaanxi Dialect Speech Database
The Shaanxi dialect speech database contains a total of 738 hours of recordings. The recorded language is the Shaanxi dialect, and the recordings were made in China. A total of 8…
Size: 738 hours
Contact for price
Chinese-English mixed reading speech data
The speech database comprises a total of 1,200 hours. The recording languages are Chinese and English, and the recordings were made in China. The sampling rate is 16 kHz, with a…
Size: 1,200 hours
Contact for price
Home Scene Voice-Controlled Word Speech Database
The home‑scene voice control vocabulary speech database was created by inviting 399 participants to record in a quiet environment using high‑fidelity microphones. A total of seven…
Size: 565 hours
Contact for price
Multi-channel Digital Speech Database
A multi-channel digital speech database, totaling 349 hours and 300,966 sentences. Recordings were made in a quiet room using mobile phones or high-fidelity recording equipment…
Size: 349 hours
Contact for price
Conference Data
The conference speech audio database contains 1,459 hours of recordings sourced from online conferences. These are authentic recordings captured at the central control console of…
Size: 1459 hours
Contact for price
Hindi speech data
The speech database comprises a total of 568 hours of recordings, in Hindi, recorded in India. The transcribed content covers ten domains, including education, technology…
Size: 568 hours
Contact for price
Chinese English Speech Dataset
A Chinese English speech database, totaling 649 hours and 516,051 sentences. Sample rate: 16,000 Hz; bit depth: 16 bits. Transcribed and annotated by professional linguists, and…
Size: 649 hours
Contact for price
Adult English speech data
A U.S. English speech database totaling 987 hours. Sampling rate: 16,000 Hz; bit depth: 16 bits. Speakers are primarily from California, New York, Washington, and Oregon. The data…
Size: 987 hours
Contact for price
Chinese children’s English pronunciation data
The children’s speech database comprises 1,709 hours of recordings. The recording language is English, and the recordings were made in China. The sampling rate is 16,000 Hz, with…
Size: 1709 hours
Contact for price
Speech Data for Young Children – Chinese
The children’s speech database comprises a total of 171 hours. The recording language is Chinese, and the recordings were made in China. A total of 1,117 speakers from various…
Size: 171 hours
Contact for price
Smart robot voice data
The intelligent robot voice database contains a total of 23 hours of recordings. The recording language is Chinese, and the recordings were made in China. The audio transcripts…
Size: 23 hours
Contact for price
Accent-Dependent Speech Database
The Accent Speech Corpus contains a total of 1,258 hours of recordings in Chinese. A total of 1,493 speakers from various accent regions across China participated in the recording…
Size: 1,258 hours
Contact for price
Mandarin Chinese Speech Database
The Chinese Mandarin speech database contains 1,000 hours of audio, with 718 hours from [ZH-CN] and 282 hours from [ZH-CN]. The recorded transcripts cover 12 domains, including…
Size: 1,000 hours
Contact for price
Infant and Toddler Crying Audio Database
The infant and toddler crying audio database comprises 68 hours of audio, totaling 2,549 recordings. The recordings were made in China, involving 544 children. All recordings were…
Size: 68 hours
Contact for price
Clinical Diagnostic and Treatment Dataset for Diabetic Retinopathy
This dataset comprises structured electronic health record (EHR) data from inpatient cases, with diabetes and its retinopathy as the core cohort, totaling 1,000 real-world…
Size: 1,000 cases
Contact for price
Accent English ASR Corpus
Supports Southeast Asian English accents, including Thai English, Indonesian English, and Malaysian English, with a signal-to-noise ratio of ≥10 dB and a word accuracy rate of 97%…
Size: 100 hours
Contact for price
Vietnamese low-resource ASR corpus
A curated collection of authentic Vietnamese audio recordings from real-life scenarios (including short and long clips), with a signal-to-noise ratio ≥10 dB and a word accuracy…
Size: 100 hours
Contact for price
Thai as a minority language ASR corpus
Selected authentic Thai audio recordings (including short and long clips), with a signal-to-noise ratio ≥10 dB and a word accuracy rate of 97%. Covering everyday life, variety…
Size: 800 hours
Contact for price
Malay minority-language ASR corpus
Selected real-world Malay audio clips (including short and long recordings), with a signal-to-noise ratio ≥10 dB and a word accuracy rate of 97%. Covering scenarios such as daily…
Size: 500 hours
Contact for price
Indonesian low-resource ASR corpus
High-quality Indonesian audio from real-life scenarios (including short and long clips), with a signal-to-noise ratio ≥10 dB and a word accuracy rate of 97%. The collection covers…
Size: 3,200 hours
Contact for price
A collection of subtitled, watermark-free videos showcasing key movements in ball sports.
Key actions in ball sports 1080p or higher No logos, subtitles, mosaics, watermarks, black borders, or noise Metadata included
$5.83per piece
A Collection of Aerial Drone Videos Featuring Scenic Landscapes
4K drone footage, landscape and travel genre
$1.95per piece
Unboxing video collection with no subtitles or watermarks
Unboxing video with no subtitles or watermarks, 1080P
$0.59per piece
Beauty and Personal Care Action Video Collection Without Subtitles or Watermarks
Beauty and personal care video, no subtitles, with watermark, 1080P
$0.59per piece
A collection of skincare and facial care tutorial videos with no subtitles or watermarks.
Facial care videos 1080P, no watermark, no subtitles, vertical format
$0.59per piece
3D scanner scan dataset
3D scanner scan data can be customized to suit the object being scanned. The output includes point cloud models, mesh models, and texture‑mapped model files. Colored white‑mask…
$3.89per set
Beauty Review Video Collection
Beauty product review videos, e.g., foundation, lipstick, primer, blush, etc.
$0.59per piece
A collection of motion‑type videos without subtitles or watermarks.
Sports and editing videos with metadata, at least 1080P resolution, 30 frames per second or higher, and no logos or subtitles.
$0.98per item
Facial Expression and Motion Video Collection
Facial expression–edited video with downward-facing metadata, resolution of 1080P or higher, at least 30 frames per second, and no logos or subtitles.
$2.92per item
Visual Effects Video Collection
Visual effects editing videos with downward-facing metadata, at least 1080P resolution, and a frame rate of 30fps or higher, without logos or subtitles.
$2.92per item
Camera Movement and Video Editing Collection
Camera shots for editing videos must include downward-facing metadata, have a resolution of 1080p or higher, and run at 30 frames per second or faster, without logos or subtitles.
$1.95per item
Amazon Product Rating Dataset
Amazon product ratings and the corresponding number of reviews for each rating
$1.95per thousand pieces
A Collection of Aerial Drone Photos from Multiple Scenarios
4K resolution Drone aerial images of various scenarios, including traffic roads, waterways, and construction sites
Size: 10,000 sheets
$0.68per sheet
First-Person Perspective Driving Video Collection
First-person view video from the driver’s seat Bitrate: 24.6 Mb/s Width: 3,840 pixels Height: 2,160 pixels
Size: 1,000 hours
$0.98per hour
Collection of Japanese Spoken Conversation Audio Files
The Japanese spoken-language training data has been formatted, and it includes metadata_split.json. Please refer to the following compressed file:
$3.89per hour
Sports Competition Video Collection
Sports‑related video Resolution: 1080p or higher Metadata information is as follows:
Size: 200,000 items
$1.95per hour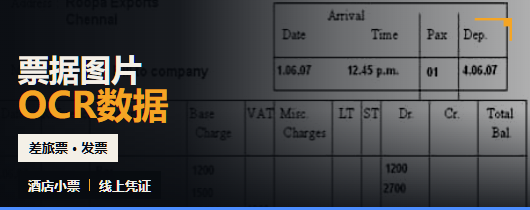
Bill Type Image OCR Dataset
Photos of travel tickets, machine-printed invoices, hotel receipts, online vouchers, overseas transaction receipts, and more
Size: 10,000 sheets
$0.10per sheet
Overseas Short Drama Video Collection
Japanese Korean Portuguese Vietnamese Thai Indonesian
Size: 100,000 episodes
$0.39per episode
First-Person Multi-Scene Video Collection
First-person HD video, featuring various scenes such as handmade crafts, shopping, and strolling, sourced from curated selections on public video platforms.
Size: 100W hours
$0.59per hour
YouTube Comment Dataset
YouTube comment data, available for customized retrieval
Size: 20 billion entries
$0.30per thousand pieces
A Collection of Solo Speech Videos in the Humanities, Social Sciences, and Arts
Speech videos in the humanities, social sciences, and arts
Size: 10,000 hours
$2.92per hour
Real-Life Short-Video Collection
Original real-person short clip, no subtitles, no logo Copyright restrictions allow use only for AI training
Size: 200 volumes
$970.15per unit
Ego Office Scene Video Collection
Office scene filming 10,000+ hours Filming equipment: GoPro Resolution: 1920*1080
Size: 10,000+ hours
$6.80per hour
Claude Opus Real-World Business Operation Log Dataset
This dataset was collected from real-world business scenarios involving nearly 600 employees across all functional roles within the company. It comprehensively captures end-to-end…
Size: 2,000 rounds
$19.41per round
Multi-Scene Hand Motion Video Dataset
All samples include clear and complete hand‑operated actions, covering the entire process of repairing multiple types of devices. The focus is on practical gestures such as…
Size: 500,000 items
$0.59per piece
Multilingual Single-Player Voice Audio Collection
This dataset covers five major languages: Chinese, English, Japanese, French, and Korean. All samples consist of single speakers delivering continuous, isolated speech, with each…
Size: 8,000 hours
$0.88per hour
Gesture Dance Video Collection
This dataset is a structured dataset of short dance videos featuring clear hand movements and gesture characteristics, with content sourced from mainstream short-video platforms…
Size: 100,000 items
$0.30per item
X (formerly Twitter) Post and Tweet Dataset
This data is structured, web-scraped information extracted from a single tweet on the X (formerly Twitter) platform. It is divided into two main modules: the outer-level tweet…
Size: 1 billion entries
$3.89per thousand pieces
TikTok Metadata Dataset (Customizable)
Customize TikTok metadata by specifying only the type
Size: 90 billion entries
$5.83per thousand pieces
TikTok Metadata Dataset
Basic information: TikTok short video, upload time, duration, language, etc.; Playback data: number of views, likes, comments, etc.; Video parameters: resolution, frame rate…
Size: 90 billion entries
$1.95per thousand pieces
TikTok Video ID Dataset
TikTok ID information without any filters Provides general-purpose web crawling for multimodal large models
Size: 90 billion entries
$0.10per thousand items
English All-Category Image OCR Dataset
This dataset covers image data of objects containing English text, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline…
Size: 9,000 sheets
$0.88per sheet
Indonesian General-Purpose Image OCR Dataset
This dataset covers image data of objects in Indonesian, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline tickets…
Size: 5,000 pieces
$0.88per sheet
Italian full-category image OCR dataset
This dataset covers images of items in Italian, including: PPTs, packaging, newspapers and magazines, forms, menus, train tickets, maps, shop signs, airline tickets, billboards…
Size: 3,500 sheets
$0.88per sheet
Spanish All-Category Image OCR Dataset
This dataset covers images of items in Spanish, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop signs, airline tickets, billboards…
Size: 4,000 sheets
$0.88per sheet
Japanese All-Category Image OCR Dataset
This dataset covers images of items containing Japanese text, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline tickets…
Size: 5,000 sheets
$0.88per sheet
Portuguese All-Category Image OCR Dataset
This dataset covers image data of items in Portuguese, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline tickets…
Size: 4,000 sheets
$0.88per sheet
Chinese Full-Category Image OCR Dataset
This dataset covers images of objects containing Chinese text, including: PPTs, packaging, newspapers and periodicals, tables, menus, train tickets, maps, shop names, airline…
Size: 3,000 pieces
$0.88per sheet
Korean All-Category Image OCR Dataset
This dataset covers images of items containing Korean text, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline tickets…
Size: 5,000 sheets
$0.88per sheet
French general-purpose image OCR dataset
This database covers images of objects containing French text, including: PPTs, packaging, newspapers and magazines, forms, menus, train tickets, maps, shop names, airline tickets…
Size: 4,000 sheets
$0.88per sheet
Russian All-Category Image OCR Dataset
This dataset covers images of objects containing Russian text, including: packaging, newspapers and periodicals, forms, menus, train tickets, maps, shop signs, airline tickets…
Size: 5,000 pieces
$0.88per sheet
German All-Category Image OCR Dataset
This database covers images of objects with German text, including: PPTs, packaging, newspapers and magazines, tables, menus, train tickets, maps, shop names, airline tickets…
Size: 4,000 sheets
$0.88per sheet
Handwritten Formula OCR Dataset
This dataset consists of images of handwritten math, physics, and chemistry formulas from junior and senior high school students, captured using mobile phones, to improve the…
Size: 100,000 sheets
$1.56per sheet
OCR dataset of handwritten primary school exam papers
This database was compiled from photos taken with users’ smartphones and primarily contains images of supplementary teaching materials for primary school Chinese and English…
Size: 50,000 sheets
$1.95per sheet
Multidisciplinary Science Communication Video Collection
Specifically designed for video understanding and cross-modal reasoning tasks, each video segment in the dataset corresponds to a single, well-defined disciplinary knowledge topic…
Size: 5,000 items
$0.98per piece
YouTube Music Audio Collection
YouTube music data Includes metadata { "title": "SUBEME LA RADIO REMIX", "artists": [ "Enrique Iglesias", "CNCO" ], "uploader": "Enrique Iglesias" } Lyrics information Súbeme la…
Size: 50 million items
$0.01per song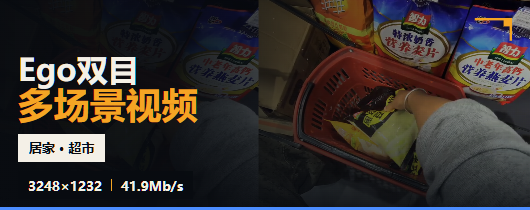
Ego-Stereo Binocular Video Collection
Live‑recorded scenes including home, supermarket, and outdoor settings, Binocular Ego video Bitrate: 41.9 Mb/s Width: 3,248 pixels Height: 1,232 pixels
Size: 30,000 hours
Contact for price
Dual-Arm Operation VR Video Collection
PICO 4 Ultra Enterprise records at 1920×1080 First-person perspective capture case video
Size: 700 hours
$11.65per hour
YouTube ID Information Dataset
YouTube ID information without selection filtering Provides general-purpose crawling for multimodal large models
Size: 20 billion entries
$0.10per thousand items
YouTube Video Metadata Dataset (Customizable)
Metadata after applying filter criteria Only the fields listed above are used as filter criteria Basic information: YouTube short video, upload time, duration, language, etc…
Size: 5 billion entries
$5.83per thousand pieces
YouTube Video Metadata Dataset
Basic information: YouTube short video, upload time, duration, language, etc.; Playback data: number of views, likes, comments, etc.; Video parameters: resolution, frame rate…
Size: 5 billion entries
$1.95per thousand pieces
Professional Exam Question Bank Dataset
Includes a comprehensive question bank covering 58 disciplines, with a total of 9 million questions. The categories are clearly organized as follows: 1. Transportation Engineering…
Size: 9 million questions
$0.16per question
Middle School Question Bank Dataset
Junior high and senior high school levels, covering all subjects—Chinese, math, English, physics, chemistry, biology, politics, history, and geography—in multiple provinces and…
Size: 10,000 sets
$1.95per set
University Question Bank Dataset
Over 500,000 subject-specific question banks for universities, covering all disciplines: physical education, military science, agriculture, chemistry, chemical engineering…
Size: 500,000 questions
$0.16per question
Elementary School Question Bank Dataset
1. A collection of high-quality exam papers across all subjects from multiple provinces and cities nationwide 2. Covers all provinces and cities nationwide, including exam…
Size: 10,000 sets
$1.56per set
University Medical Examination Question Bank Dataset
A question bank dataset for the four-year medical curriculum, comprehensively organizing course modules by year—freshman through senior—and outlining their learning objectives and…
Size: 400,000 questions
$0.16per question
Fight Scene Video Collection
1. Duration: 5–15 seconds, with data for both single-shot and multi-shot videos 2. Features a complete storyline 3. Includes complex的动作 4. Cinematic‑level camera movements 5. Year…
Size: 200,000 items
$0.98per piece
Ego Factory Assembly Line Video Collection
Head-mounted camera capturing first-person (egocentric) industrial video No existing dataset Records the entire workflow of production-line assembly, quality inspection, and…
Size: Monthly production capacity: 5,000 hours
$15.53per hour
Ego Home Scene Video Collection
Kitchen scenes, room scenes, hotel scenes 10,000+ hours Camera: GoPro Resolution: 1920*1080
Size: 90,000 hours
$6.80per hour