OCR dataset of handwritten primary school exam papers
About this dataset
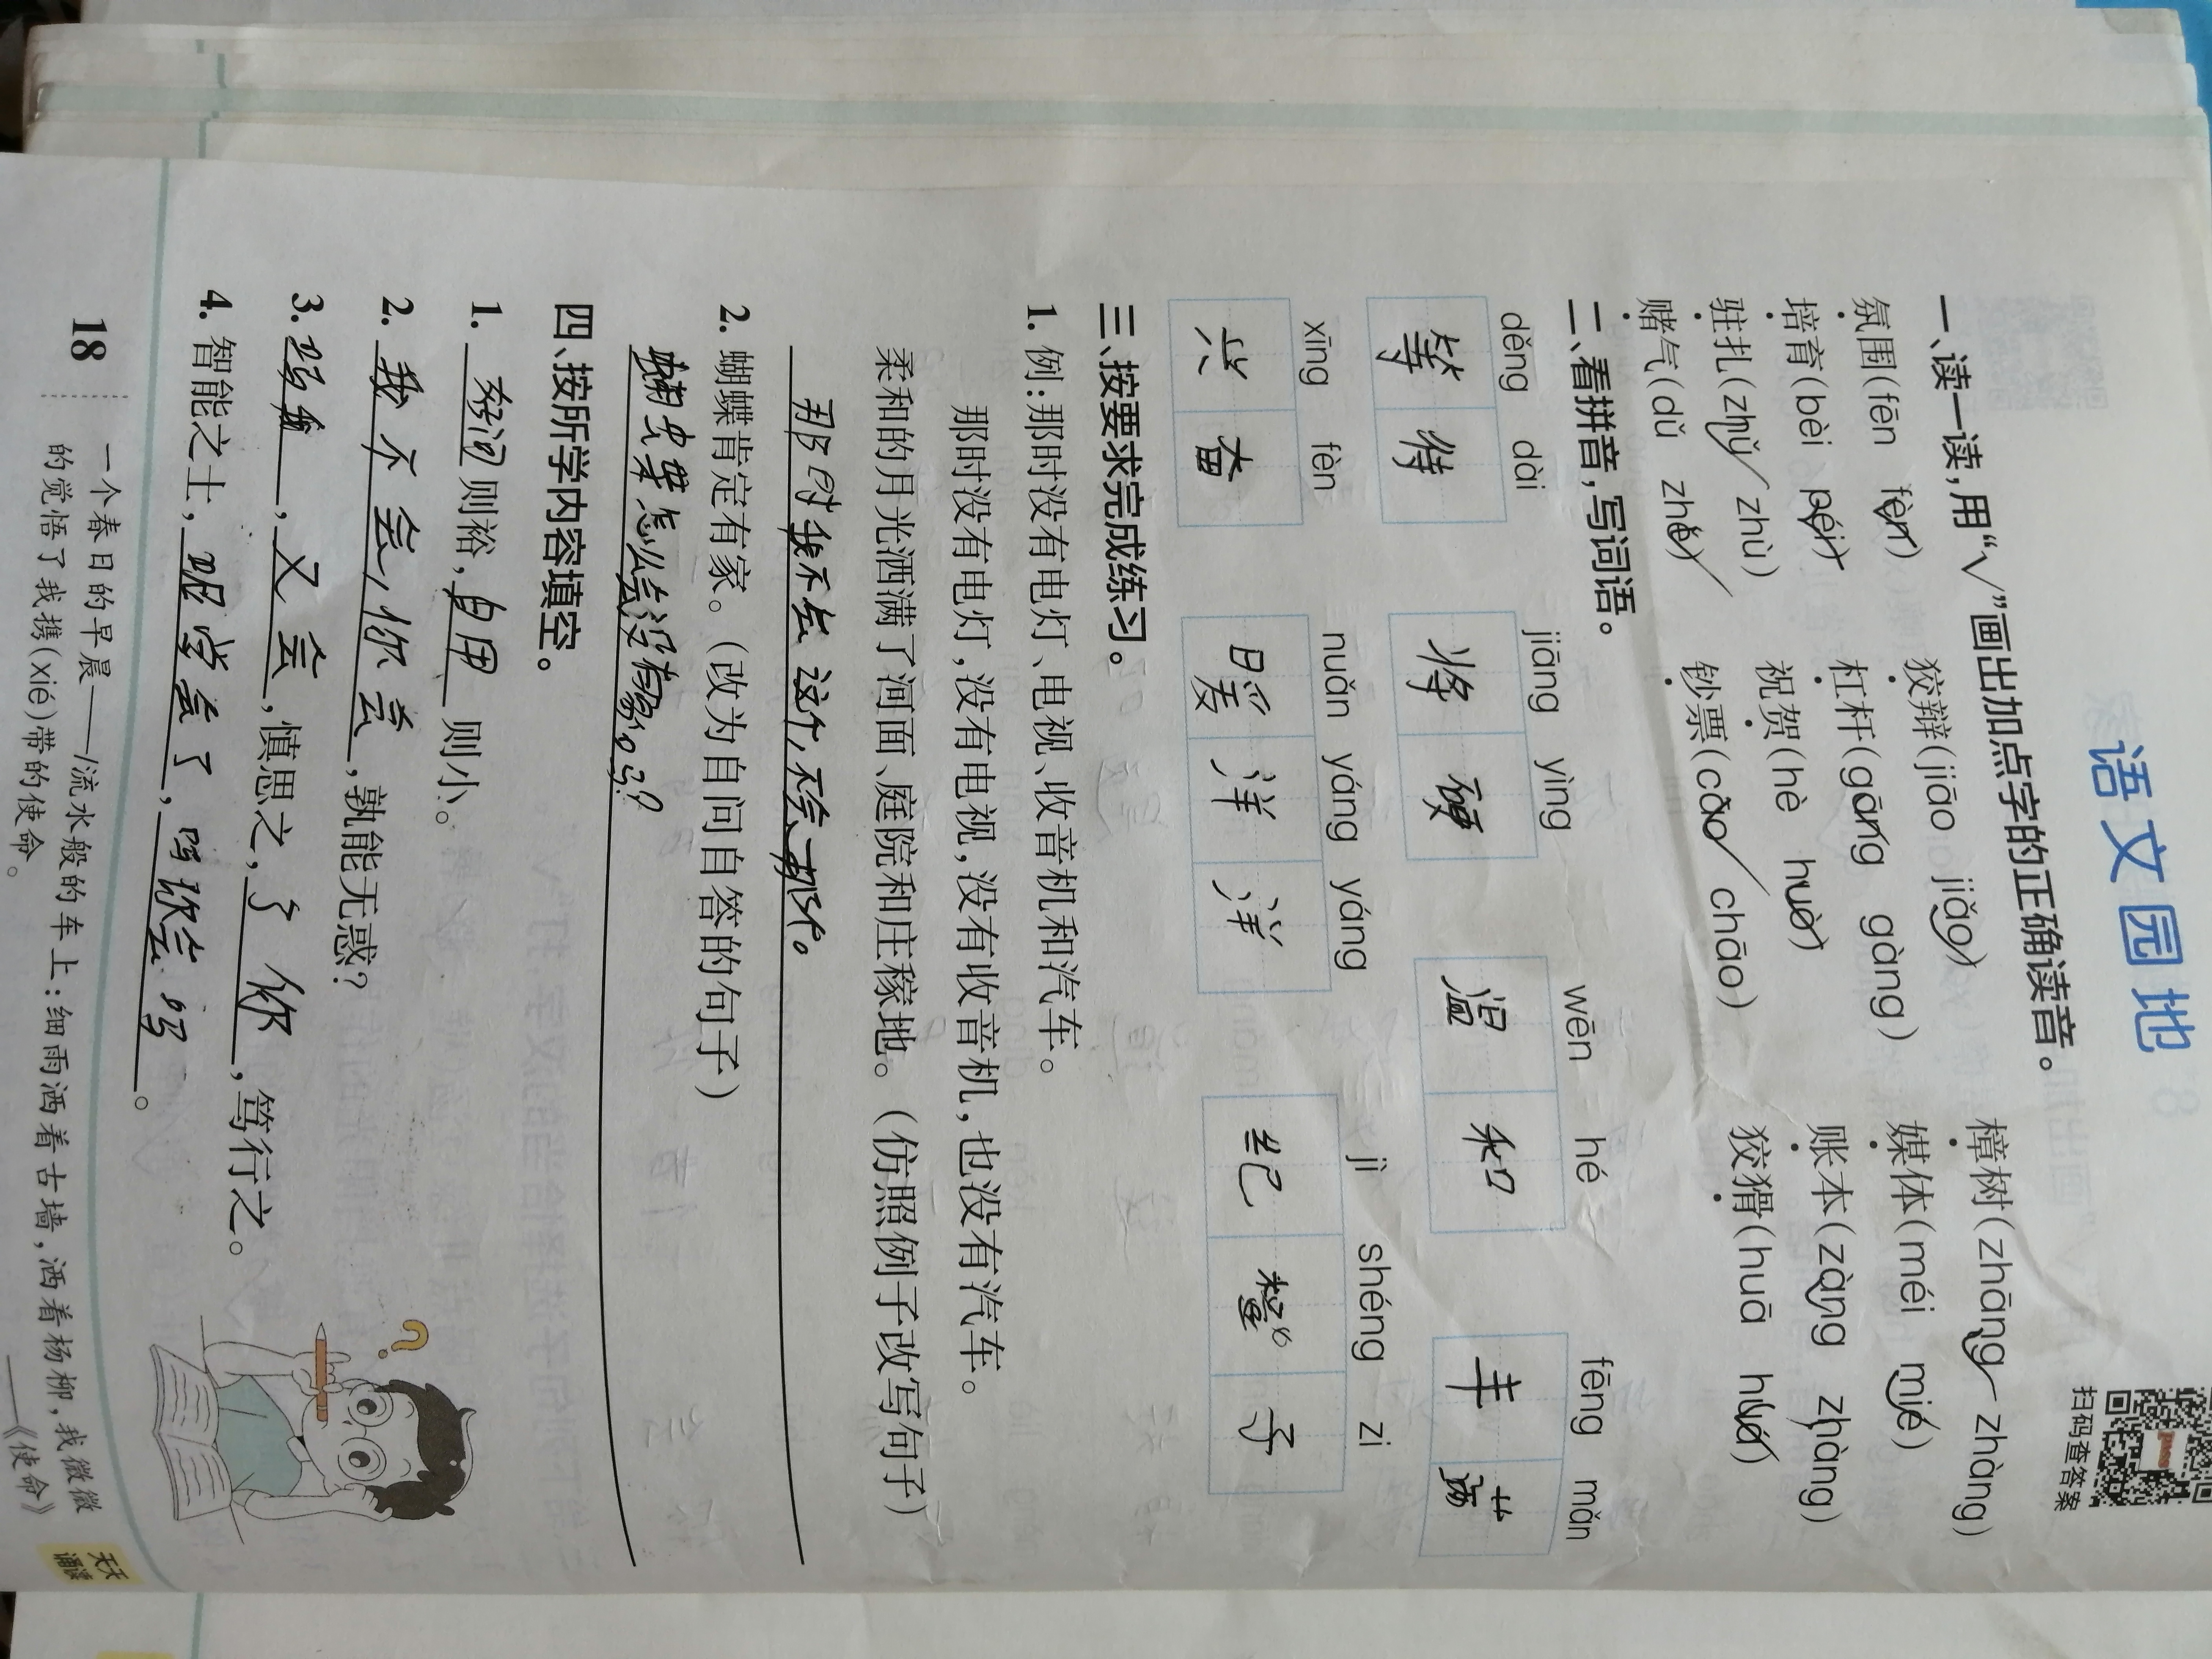
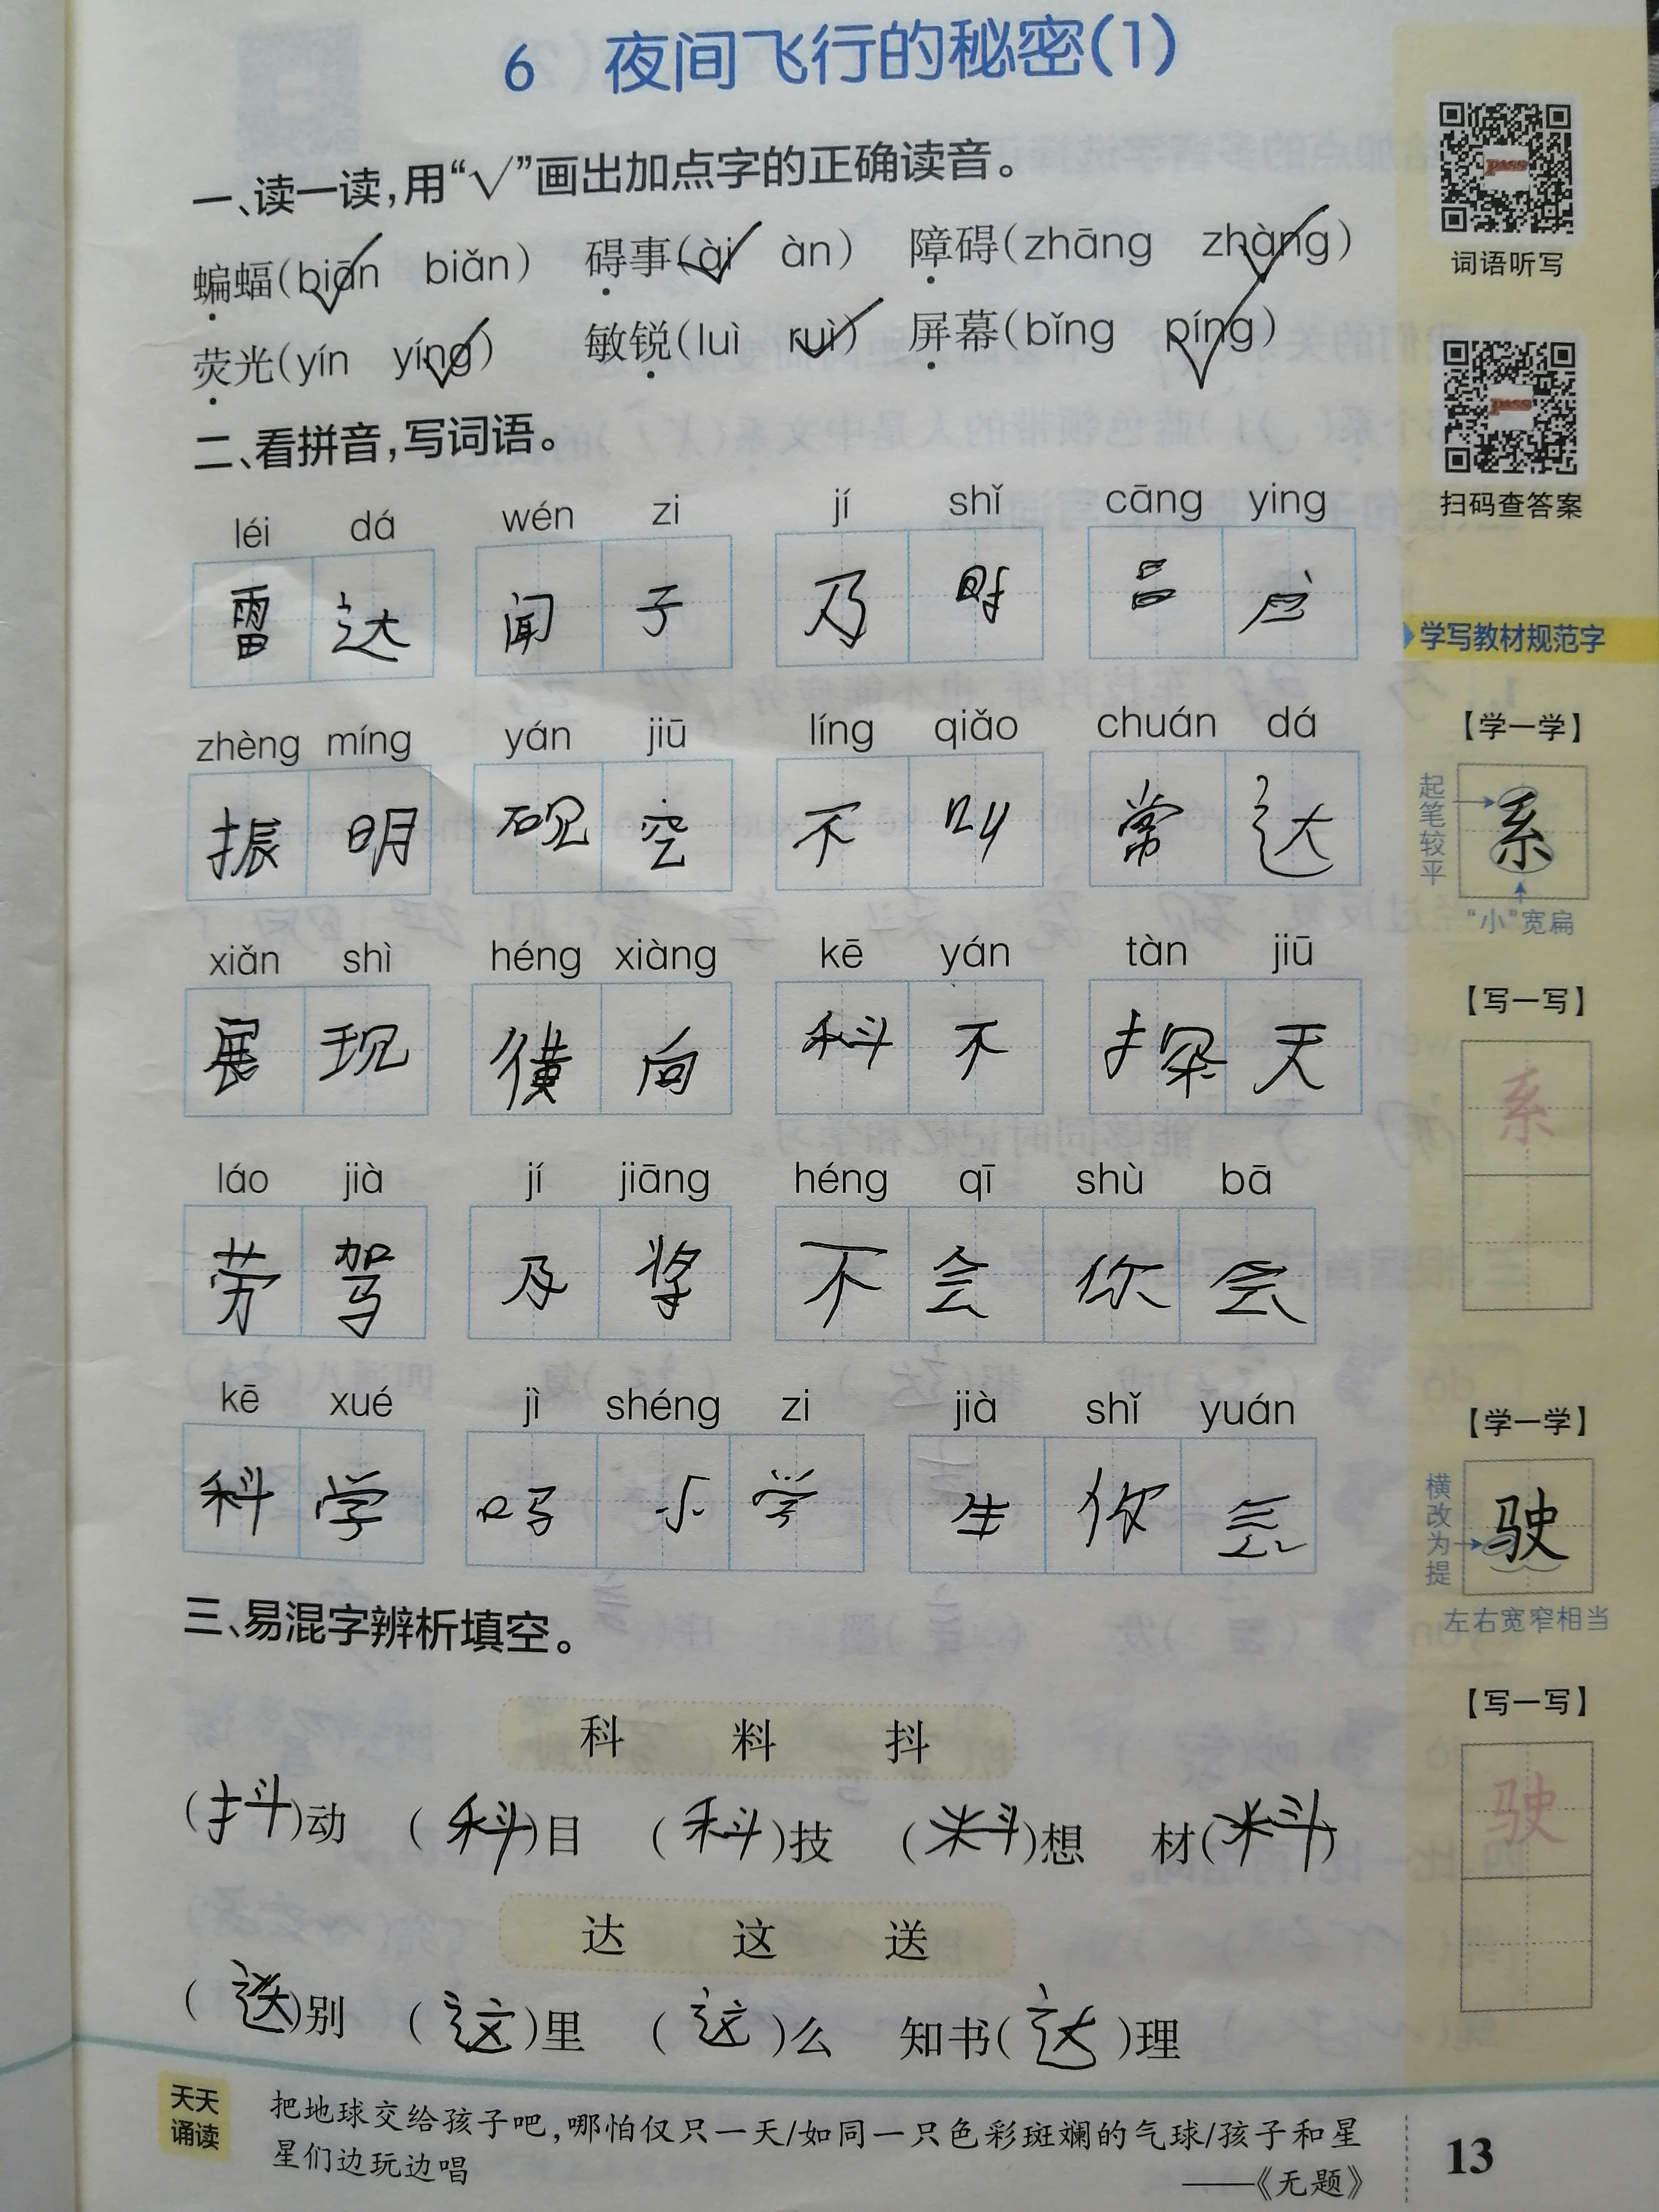
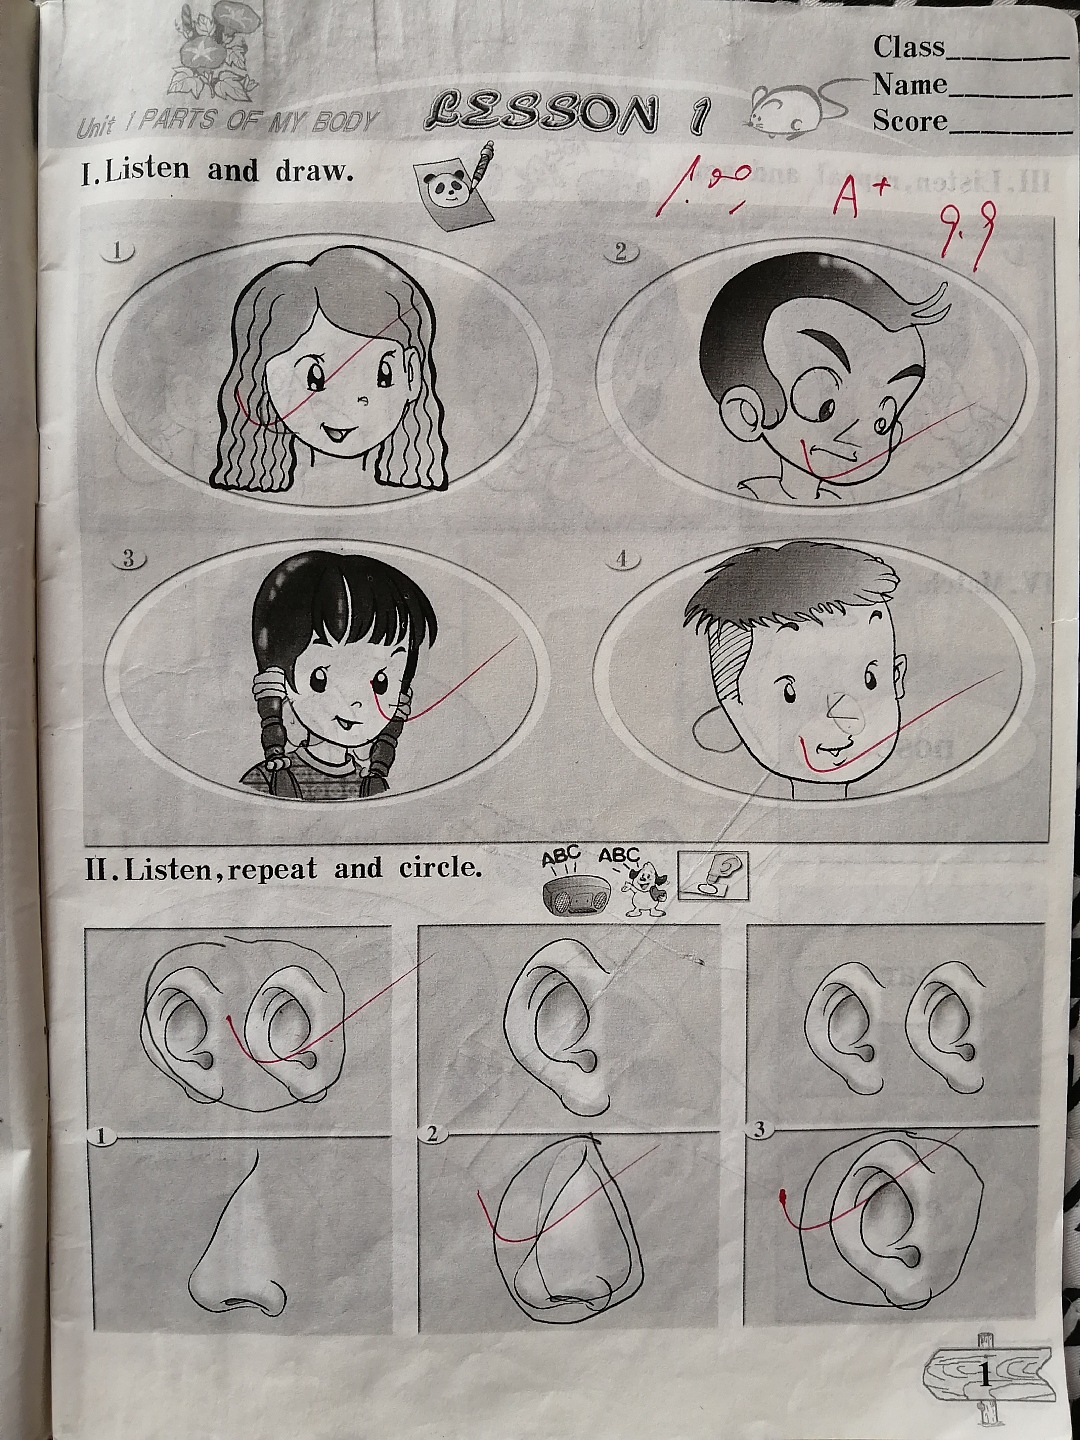
This database was compiled from photos taken with users’ smartphones and primarily contains images of supplementary teaching materials for primary school Chinese and English, focusing on key Chinese characters, classical poetic imagery, as well as high-frequency English vocabulary and situational dialogues.
1. Subjects Collected:
Chinese (42,725 images), English (13,093 images)
The data has been anonymized and captured in high resolution using smartphones, intended for OCR recognition.